Wednesday, January 18, 2006

Two breakthroughs per century per billion people

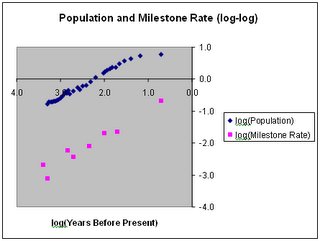
Chart of population growth and milestone shift rateRay Kurzweil argues that human technology is accelerating exponentially in part by referring to data which shows the shrinking time interval between “paradigm shifts”. He ascribes this acceleration to cumulative complexity feeding on itself. (The Singularity Is Near: When Humans Transcend Biology, Ch. 1, p18 ff). There’s a scan of the Kurzweil chart in Kevin Drum’s blog post. It’s worth reading, if only for Kurzweil’s admission in a reply post that this past acceleration does not imply that there will be continued acceleration in the future.

There’s a simpler explanation, however: the exponential acceleration of paradigm shifts can be entirely accounted for by the exponential growth in human population. More people, more brains; more brains, more frequent shifts.

Kurzweil builds on data Theodore Modis collected on the growth of complexity and change. Modis lists “canonical milestones” in the history of the universe. (The Canonical Milestones in the chart on p20 of Kurzweil don’t correspond exactly to the list in Modis’s paper; I’ve used the dates in Modis.) To facilitate comparison with population growth, I use the rate at which the milestones occur rather than Kurzweil’s “Time to Next Event” parameter. The one is the inverse of the other; as one gets closer to the present, the Time To Next Event shrinks, which means that the rate grows.

In my analysis (see spreadsheet for detailed workings and the source data), I plotted the occurrence rate for the “canonical milestones” and against human population growth on the same log-log chart; see graphic above.

The result is uncanny: to within the errors of this very squishy data, the two lines have the same slope. That means that the ratio between the rate of milestone occurrence and human population is constant, at roughly two milestones per century per billion people over the last two thousand years. If one makes the jump from correlation to causation, the driving force is simple: More people means more innovation.

Occam’s Razor applies here. If one can explain the growth in the breakthrough rate by invoking increasing population, and without invoking some mystical acceleration of order and complexity, one should do so. An increase in complexity is a consequence of increased innovation, but it’s not obvious that’s it’s the only cause.

Kurzweil points out in Kevin Drum’s blog that one shouldn’t extrapolate a log-log curve like this one. However, we now have a model for why the data behaves this way, and we can predict that a slowing down in the population growth rate will lead to a slow-down in the shift rate. This contradicts the thrust of Kurzweil’s argument, which is that cumulative complexity will lead to an ever-faster shift rate.

Even if the ratio between paradigm shift rate can’t be completely explained by population growth, the “more brains” effect should be factored out of the data before one tries to draw conclusions about accelerating complexity.

Complexity being driven by a simple input like population suggests that other exponentials that Kurzweil observes, eg Moore’s law, may also be due to growth in inputs, eg exponential increases in financial investment leading to bigger bang for the bucks in silicon chips.

I’ve only looked at the last two thousand years. Kurzweil and Modis make a far more radical claim: that major shifts in the entire history of the universe, from the Big Bang to the Internet, can be plotted on a single line with a constant rate of exponential growth over ten billion years. The implication is that there is a single accelerating process that underlies all phenomena – things as diverse as cosmogony and technology innovation. I find this a stretch. The data is suspiciously neat, but let’s stipulate it; the question then is: Are there other ways to explain the curve?

I suspect that the underlying reason is the selection process; humans consider exponentially fewer and fewer things to be interesting as they look back in time from the present moment. We believe that our vantage point is privileged. Ptolemaic astronomy put the Earth at the center of the universe. When we put our moment in history at the center, I call it the Special Present Fallacy. More on this in a future post.

Sunday, January 15, 2006

Rilke on patience

Rainer Maria Rilke sets great store by patience. (I recently discovered Rilke’s Letter to a Young Poet, thanks to Natalia Ilyin.)

For Rilke, personal development is an organic process that should be allowed to take its own course. From Letter Three, in the Stephen Mitchell translation:

Always trust yourself and your own feeling, as opposed to argumentations, discussions, or introductions of that sort; if it turns out that you are wrong, then the natural growth of your inner life will eventually guide you to other insights.

Allow your judgments their own silent, undisturbed development, which, like all progress, must come from deep within and cannot be forced or hastened. Everything is gestation and then birthing. To let each impression and each embryo of a feeling come to completion, entirely in itself, in the dark, in the unsayable, the unconscious, beyond the reach of one's own understanding, and with deep humility and patience to wait for the hour when a new clarity is born: this alone is what it means to live as an artist: in understanding as in creating. In this there is no measuring with time, a year doesn't matter, and ten years are nothing.

Being an artist means: not numbering and counting, but ripening like a tree, which doesn't force its sap, and stands confidently in the storms of spring, not afraid that afterward summer may not come. It does come. But it comes only to those who are patient, who are there as if eternity lay before them, so unconcernedly silent and vast.

This is commonplace spiritual advice. And yet, so is “live for today”, the notion that if one were to die at midnight, every experience would be lived to the full.

Perhaps the paradox can be resolved through mindfulness, which is perhaps hardest of all: Live this moment to the full. Mindfulness follows from an understanding that one can only live in the present. Since one only lives in the present, there is no experiential time to be measured: you are always standing at the same place holding the tape measure.

Thursday, January 12, 2006

Kurzweil proves that the amount of love in the world grows exponentially

Love is all you needThe amount of love in the world grows exponentially over time, and I can prove it – just as well as Ray Kurzweil can prove that computational power grows exponentially.

My argument takes the exact same form of Kurzweil’s in the appendix “The Law of Accelerating Returns Revisited” in his book The Singularity is Near (P 491-2).

We are concerned with three variables:

H : the happiness in the world (measured by the Oxford Happiness Inventory or the General Happiness Questionnaire, say)

L: the amount of love in the world as it pertains to happiness

t : time

We observe that happiness is proportional to the amount of love in the world [in a more loving world, people are happier].

(1) H = aL

The rate of change in the amount of love in the world is proportional to the amount of happiness [the amount of love increases more rapidly if people are happier].

(2) dL/dt = bH

Substituting (1) into (2) gives:

(3) dL/dt = abL

The solution to this is:

(4) L = L0eabt

And thus L, the amount of love in the world, grows exponentially with time (e is the base of the natural logarithms).

I have only changed the symbols and a few words. The text above, from “We are concerned with three variables…” onwards, is excerpted from Kurzweil verbatim, with the exception of the glosses in square brackets which are mine. (My glosses have to stand in for the argumentation in large tracts of Kurweil’s book.)

Instead of H, Kurzweil uses V, defined as the “velocity (that is, power) of computation (measured in calculations per second per unit cost).” Instead of L, he has W, defined as “world knowledge as it pertains to designing and building computational devices.” I substituted the constants a and b for his c1 and c2 given the difficulty of writing equations in HTML.

A major flaw in my “proof” is that one can’t measure love; hence, an equation like (2) is utterly meaningless. Consequently, the whole argument is meaningless.

The same flaw applies to Kurzweil’s argument. Since “world knowledge” is nowhere defined, his version of equation (2) (dW/dt = c2V where W is world knowledge and V is velocity of computation) is similarly meaningless.

Wednesday, January 11, 2006

Everyday patents - night light

GE Limelite
The GE Limelight night light package notes that it is covered by US patent 5,662,408, “Simple plug in night light having a low profile”. I was suprised to discover that this patent doesn’t cover the lamp’s technology: electroluminescence. Rather, the novelty is that its design is simple to manufacture, and thus cheap.

The patent abstract is so simple that it’s worth quoting in full: “The night light has a case with a front side and a rear side. The front side of the case has a portion defining a window. The lamp is secured between the sides and covering the window. The lamp has conductors for connecting to an electrical supply which are in electrical contact with a first and second blade, the blades extending from the rear exterior face of the case for engaging an electrical outlet. The blades are held in a slot through the rear side of the case and by a portion of the blades which engages the interior face of the front side of the case.”

The inventor, Joseph Marischen, has four other patents to his credit. Three are for other night light designs, and one is for an Animal training method using positive and negative audio stimuli.

Overall, there is no shortage of filings in the technology area: a search on the USPTO database gives 1655 hits for patents with “electroluminescent” in their title.

Monday, January 09, 2006

Extending software patents: Those who live by the sword, die by the sword

The software industry is poised near the top of a slippery slope. Aggressively extending software patents around the world will be disastrous for software giants, confounding their expectations. I believe that our intuitions fail us with intangibles like software, and we don’t yet have enough tools and experience to make good strategic decisions.

It will take time for the adverse impacts to appear, but they will materialize at an exponential rate, matching the combinatoric structure of software programs. (Non-linear growth is another area where our intuitions are not very good.)

For the avoidance of doubt: I’m not against intellectual property rights, nor do I believe that software patents in particular are illogical or immoral. They may be imprudent, though.

In an eight page note on my web site I argue as follows:
  1. The economics of software patents is qualitatively and quantitatively different from previous intellectual property. Since there is no good metric for knowledge, and since our intuitions are weak, companies are underestimating the costs of an extensive patent regime.

  2. Companies that see themselves as technologists will lose control of the development process, ceding power to patent lawyers and off-shore developers.

  3. It’s necessary to make a return on investments in innovation. However, patents are the wrong tool for large software companies because they address only a tiny part of the innovation process, and a part where these companies do not have a competitive advantage.

  4. Software patents have some utility as a defensive strategy, but fail to deal with patent trolls, the biggest threat to software giants

  5. We didn’t encounter this problem with earlier technologies because life cycles were longer, and products didn’t consists of endlessly interlinked components

Software takes us into uncertain realms of law and philosophy. It is advisable to tread carefully in extending the current intellectual property regime. I recommend that large software companies do the following:
  1. Back off their initiative to extend the scope of software patents, both in subject matter and global coverage. I’m not arguing that such an expansion is illogical, just that it’s inadvisable given our current ignorance. Large companies like Microsoft are taking the lead, and are creating the very situation that they may come to regret: Those who live by the sword, die by the sword.

  2. Rely on copyright rather than patents to protect their innovation. It’s a better fit with their strengths in the innovation process.

  3. Support and advocate the limited time coverage for both patents and copyright on software. Terms should be just long enough to recoup investment on v1 products; inventions should move into the public domain pool so that everyone (including the software giants themselves) can re-use in recombinant ways for later versions.

Sunday, January 08, 2006

Armor is making a comeback

15th C Gothic cuirassThe Pentagon believes that more upper body armor could have saved most of the Marines who died of upper body wounds in Iraq (Pentagon Study Links Fatalities to Light Armor, New York Times, 7 Jan 2006).

Surprisingly, we may be returning to an era of armored warriors. Most US troops in Iraq already wear ceramic plates to protect their chest and back. When troops started hanging their crotch protectors under their arms, the Army shipped out plates to protect their sides and shoulders.

The invention of the gun seemed to make armor obsolete: ballistic chemistry had triumphed over materials science. However, materials chemistry has been advancing rapidly (Kevlar, ceramics), and we can expect nanotechnology to accelerate the pace. While bullets are no doubt being redesigned to penetrate body shields, I expect that personal armor will become more widespread. We’ll also increasingly see it in non-military applications – some bull riders already wear protective vests, race car drivers will start wearing armor, and there may eventually be requirement for kids on bikes.

The current ceramic or Kevlar plates seem more like Japanese armor than the moulded suits worn by Medieval knights. As technology improves, we’ll see more rounded shapes. The Star Wars design team was prescient; the Imperial Trooper armor, particularly the helmets, seems inspired by the shapes of samurai armor. The DARPA exoskeleton armor looks uncannily like something out of the movies.

As the US Army adopts armor, old battle tactics re-emerge. At Crecy and Agincourt, the largely unarmed English archers defeated heavily armored French knights. While arrows may not have penetrated the knights’ armor at long range, the horses weren’t as well protected. An unhorsed knight floundering in the mud was at the mercy of bare-legged English soldiers. The US is learning all about asymmetric warfare…

Saturday, January 07, 2006

Broadband Futures 4 – Rethinking the Categories

My previous posts have made certain assumptions about the structure of the US Internet debate. While the “pipes vs. content” view is commonly used, it locks one into a worldview that may not yield the most creative solution. Looking at the players in different ways reveals unexpected alliances, eg Comcast and Yahoo vs. boingboing and Disney.

In Broadband Futures 1 - Who Pays? I listed the following key players: customers, network operators, and content providers. One can further subdivide each of these categories:
  1. ‘Passive’ customers, who want to access entertainment, and ‘active’ customers, who participate in a peer-to-peer web of content production

  2. Cable companies (eg Comcast, Cablevision, Time Warner) and telephone companies (eg Verizon, SBC/AT&T, BellSouth)

  3. ‘Establishment’ content providers (eg eBay, Google, Disney), and ‘independent’ content providers (eg the ‘active’ customers above, and sites/services like bittorrent, torrentreactor, boingboing, digg).

The underlying assumption in this categorization is that the world is divided into transport and content. This is the conventional classification:
Pipes – Content
The flaws in this assumption lead to other categorizations. (I’ll stick with binary divisions for now; breaking out of a dichotomy is another useful exercise.)

Cable companies view themselves as the providers of an integrated entertainment and communications service to their customers. They’re not just a dumb pipe, they would contend; they add value by aggregating content into bundles their customers want to consume. The telephone companies have traditionally been Pipes, not Aggregators, but they’re adopting the latter stance as they begin to compete with the cable companies in video entertainment. This leads to the following categorization:
Aggregators – Originators
At first blush this classification doesn’t significantly change the players in the Pipes/Content view – one might say it’s just a change of name. However, many players in the Content group are more aggregators than originators, like Yahoo and MSN, link compendiums like del.icio.us and digg, and directories like mininova and ed2k-it.

The distinction between passive and active consumers points to division between centrally controlled commerce and ad hoc, distributed mass media. Let’s call this classification:
Oligarchs – Productive Masses
The ‘oligarchs’ are the large companies with economies of scale; the ‘masses’ are the bubbling multitudes for whom the Internet has given a distribution medium they didn’t have before. This division splits up the aggregators into Comcast and Yahoo on one side, and del.ico.us (before its acquisition by Yahoo – a telling development…) and bittorrent on the other. Large studios like Disney fall on the one side, and small independents on the other.

Another way to break open the conventional categorization is to consider:
Facilities – No Facilities
The netops are clearly facilities owners, and consumers don’t own network facilities. However, some of the content players do own network facilities (Yahoo, eBay), while others (Disney, boingboing) don’t. Large P2P operations like bittorrent and ED2K are large facilities in aggregate, but they are amorphous; they don’t fit easily into either category, but I treat them as facilities owners.

One can keep going indefinitely, but I’ll stop here with only a mention of a few other classification options that can refine this analysis:
  • Retail content (eBay) vs. Media content (Yahoo)
  • Brick-based retail (Wal-mart) vs. pure online retail (Amazon)

One can summarize these shifts in a table. For simplicity I’ve picked some specific outfits to represent larger constellations:
  • Comcast: network operators, representing cable operators as well as telcos like Verizon and BellSouth

  • Yahoo: portal, ecommerce and search, representing the likes of Google, eBay, Amazon and MSN

  • Boingboing: independent content producers – the blogosphere

  • Disney: established content producers, representing the music and video studios

  • Bittorrent: a placeholder for a constellation of P2P players and technologies, including content directories like mininova and applications like Azureus
Here's a table of with examples of players in the various classifications:

Distinction A – B

Category A

Category B

Pipes – Content

Comcast

Yahoo, bittorrent, boingboing, Disney

Aggregators – Originators

Comcast, Yahoo, bittorrent

boingboing, Disney

Oligarchs – Productive Masses

Comcast, Yahoo, Disney

boingboing, bittorrent

Facilities – No Facilities

Comcast, Yahoo, bittorrent

Disney, boingboing


One can see some consistency in the way I’ve arranged the table: Comcast (and its ilk) is always on the left, and boingboing (& Co) is always on the right. However, unusual alignments also appear, eg Comcast, Yahoo and bittorrent vs. boingboing and Disney in the “Aggregators-Originators” perspective.

In fact, boingboing and Disney are aligned more often than not: this is ironic given the high profile “copyfight” argument that pits the establishment and independent content providers against each other. When it comes to network neutrality, Jack Valenti and Cory Doctorow will need to find a way to work together in their common interest (see King Content vs. the Copyfighters and From copyfight to copytruce)

Friday, January 06, 2006

Internet One and Internet Ten

We’re at a watershed between today’s US broadband performance, and what’s about to be delivered. Since it’s roughly an order of magnitude difference, I use the terms Internet One and Internet Ten.

Internet One
  • Throughput: a few Mbps

  • Download/upload volume: a few GB/month

  • Latency: no guarantees
Internet Ten
  • Throughput: tens of Mbps

  • Download/upload volume: tens of GB/month

  • Latency: tenth of a second or better

Internet One is fine for today’s services; web pages load quickly, and few web users download more 3 GB of files per month. However, once video comes into play you need Internet Ten: 4-6 Mbps throughput for HDTV quality video, and/or tens of GB/month to download movies. The quantitative change in network performance leads to a qualitative change in user experience and business models.

Examples:
  • Usenet file sharing: Internet One. Bittorrent: Internet Ten.

  • Google Search: Internet One. Google Video: Internet Ten.

  • CNN.com thumbnail videos: Internet One. TV from your phone company: Internet Ten

Wired networks will always be an order of magnitude (or more) faster than wireless ones. However, it’s significant that we’re at the point where cellular companies are moving from Internet Zero (100 kbps) to Internet One speeds on a per-customer basis. (While Wi-Fi and 3G offers Internet Ten throughput from every bases station, the per-customer performance is still Internet One.) Customers who are satisfied with Internet One applications will have a choice of many competing providers; those who need Internet Ten will still face a cableco/telco duopoly.

Broadband Futures 3 – The Big Twelve Deal

Doing the deal
I argued in Broadband Futures 2 – The Half & Half scenario that a mix of proprietary and open access Internet was the most likely outcome for consumer broadband in the US. However, it will require content players to negotiate bilateral deals with network operators to get decent network performance, which will be messy and difficult.

Simplifying Internet transit negotiations

It may be in the interests of a few big app/content players (the big boys) to band together to make a lump sum payment the network operators (netops) to provide open access to all, rather than negotiating special access on a case-by-case basis. This deal would benefit all app/content companies, since it would reward netops that provide a non-discriminating Internet pipe to all comers.

It might seem counter-intuitive for the big boys to do this, since only they would be paying the netops, while all Internet players, including their competition, would benefit. However, it can sense because (1) the big boys would derive enough benefit for themselves to make it worth their while; (2) the big boys will buy up the most interesting small fry, eventually (cf. Yahoo buying Flickr and del.icio.us, eBay buying Skype, and Google buying Blogger).

The players

The netops are strong because there are essentially only six of them nationwide: Comcast, Cablevision, Times Warner on the cable side; and Verizon, SBC (newly renamed AT&T) and Bell South on the telco side. Further, in any given locality a netop has at most one high speed broadband competitor: a residential customer has to choose between the one local cable company and the one local phone company.

There are thousands of app/content companies on the other side of the table. For the deal to work, one needs a small group of negotiators; too many cooks, etc. However, the group needs to be large enough group to cover all the key players. The obvious three big boys are the top Internet revenue companies: Amazon, Google, and Yahoo (revenues of $8.1, $5.2 and $4.8 billion, respectively). If one could fit three more around the table, I’d pick eBay ($4.2 billion), Microsoft ($2.2 billion MSN revenue, $40 billion total), and Wal-Mart. (Wal-Mart’s revenues are $300 billion; I haven’t figured out what percentage is generated online, or how the margin compares to that of the pure online players. However, I assume it’s comparable to the other big boys, that is, in the $4 billion range.)

The deal

So now we have six netops and six Internet content companies at the table: the Big Twelve. Here’s what a deal might look like:

1. The big boys pay the netops a lump sum in return for a guarantee that their Internet offering won’t discriminate among content providers. It might not be quite as big as the aggregate deals that the netops could negotiate piecemeal, but transaction cost would be significantly lower.

2. It should be big enough that if the big boys could use the money to build their own open access “third pipe” if the netops didn’t play ball.

3. The payment would be a percentage of gross US Internet revenues, payable on the basis of bandwidth provided per customer; this would provide an incentive to the netops to add bandwidth

4. In return, netops wouldn’t sign sweetheart deals with any providers, not only the big boys but any content provider. There would be no covert advantaging of one provider’s content over the others.

5. If there are value added services, there would be a standard rate card; if one provider negotiated a price for, say, local caching, any other player could get it for the same rate. (If the content side plays its cards well in DC the coming months, they may be able to force such a rate card requirement on netops regardless of a deal.)

Tweaks

The big boys have additional leverage with the three telephone companies, since the content companies buy significant amounts of internet backhaul capacity. They could decide to allocate their backhaul purchases in a way that aligns with their other strategic interests (or whatever the formulation would be that would avoid anti-trust problems).

I have my doubts that twelve is too large a group of parties for a negotiation. If one limited it to the three telcos, and a subset of the six content big boys, the odds of success would be better.

Straw man numbers

To get a feel for the deal, assume 50 million US households covered by the payment, and that the big boys pay the netops $2/subscriber/month; that amounts to $1.2 billion/year. With the big boys’ aggregate revenue at around $30 billion, that’s a painful but not excruciating toll. The six year net present value at a 10% discount rate of this cash flow is $5.2 billion, which is enough to overbuild 10% of the 50 million broadband households, at $1,000 a pop – with suitable cherry picking, this threat to their margins could be enough to keep the netops at the table.

Terminology upgrade: “Recursively non-rival”

Matrioshka
I defined the term “doubly non-rival” in Knowledge as a factor of production: software has this curious property that it not only has non-rival knowledge as its input (the know-how of its programmers), but the product itself is non-rival, too.

This is important because one can easily create a chain of software products, one nested inside the other. In contrast, rivalrous physical “if I have it, you can’t have it” products cannot be infinitely composed, one within the other. Software is built by indefinite accretion, as demonstrated in the constant “wrapping” of old code components in new interfaces. A physical product can contain thousands of ideas, but its size is limited. If one can’t use one of its components (let’s say because of a patent infringement claim), it relatively easy to substitute another. The dependencies in software products are much more complex; see eg Software project management: an Innately Hard Problem.

I’m grateful to Peter Rinearson for suggesting a better term: “recursively non-rival”. This more accurately captures the combinatoric accretion of knowledge in software.

Thursday, January 05, 2006

Broadband Futures 2 – The Half & Half scenario

GryffonThe regime governing the next generation of broadband consumer services in the US is up for grabs. Broadband Futures 1 - Who Pays? introduced the players and their motivations. I now turn to how the game might play out. I’ll argue that the most likely outcome is an uneasy mix of proprietary services and traditional Internet access.

I outlined elswhere (Word document, free Word viewer) the pros and cons of four scenarios that span a range of possible futures. To summarize:
  1. “Utility”: Unfettered access to all content over a regulated pipe

  2. “Club Med”: A completely managed experience controlled by the network operator

  3. “Half & Half”: A mixed model where a walled garden and open access Internet co-exist

  4. “Profit Sharing”: Network operator sells Quality of Service interfaces to all comers

The most likely outcome: Half & Half

In the Half & Half scenario, a network operator’s bandwidth is split between “proprietary” services, and “open access Internet” that is more or less strictly regulated by the FCC.

The proprietary side will offer a bundle of entertainment and Internet services with premium performance. For example, the response time on the on-line games offered on the proprietary side will be better than those obtainable on the “open Internet” side. The bundle will probably include multi-channel video, telephony, and on-line games.

The Internet side will be sold as a series of quality tiers; customers will have to pay more if they want better performance. A key question will be whether there will be tiers that would allow 3rd party providers to compete with proprietary offerings, eg in offering a multi-channel video service that competes with the netop’s. Tiers can be constructed to minimize competition, by making the network capabilities required for competitive offers unavailable or expensive; they include caps on throughput speed (to limit streaming TV offers), latency (telephony), and monthly down/upload bandwidth (P2P video services).

It is unlikely that customers will be able to buy “naked” Internet without buying proprietary service. With sufficient legislative pressure there may be forced unbundling, but the naked internet that customers might get will be pretty lousy, e.g. 1 Mbps max throughput, 2 GB/month maximum upload/download, no guarantees that voice or video streams will not be interrupted. In other words: you’ll be able to browse Wikipedia OK, but media intensive sites will be slow, you won’t get decent video streams, Internet telephony won’t work, and you won’t be able to participate in (legal) media file sharing.

Complications

Even if suitable tiers offered, the netop could make them so expensive that 3rd party services wouldn’t be competitive with the proprietary offer; for example, the proprietary bundle, which includes video, could cost $50/month and include video, whereas the tier that could support 3rd party video streaming might cost the consumer $47, leaving the 3rd party video provider with at most a $3 revenue opportunity.

Regulation to manage competition between the netops and 3rd parties would be clumsy at best; it will inevitably devolve to price control. If the government specifices but doesn’t set prices for specific tiers of service, a netop could price the relevant tier so high that services offered over it wouldn’t be competitive with their proprietary offer.

Some content will be more equal than others on “Open Internet” side. Customers will be able to access all content on the net, but providers will be able to buy better performance. Customers will be un aware of this activity. They might notice, for example, that Fox News video streams may be interrupted less than CNN’s, or Sony on-line games may have lower latency than X-Box – but they won’t know that it’s because Fox and Sony have struck a side deal with their netop. There may also be “tier hopping”: Real Networks could pay BellSouth a premium to ensure that a Rhapsody media stream gets Platinum Tier treatment even though a customer has only paid for Silver Tier network performance.

Striking deals

This situation will motivate app/content companies like Fox and Sony to strike alliances with netops like BellSouth. It will be tough to get nationwide deals, though. While there is a local duopoly in broadband access (at most one cable company and one telephone company for a given household), there are more players nationally. No netop has a nationwide footprint. In each market there will be (at least) three content players trying to get exclusives with (at most) two network operators, and nobody will be able to sign one deal to cover the entire country.

It’s therefore unlikely that any content player will be able to lock up all markets. This may lead the big content players to try to strike a national deal with the netops – the subject of a forthcoming post.

When’s a win not a win?

Mark Brown celebrates Longhorn victoryThe University of Texas Longhorns beat USC in the Rose Bowl last night. OK, so I’m a little partisan, but 41-38 is so close that if this were The Other Football (aka soccer) it would be a draw.

When a game is won, journalists find endless explanations for why the winning team won. But in a very close game it could easily have gone the other way, and they would presumably then have found good reasons why the other team won. (The generalization to the writing of history is left as an exercise for the reader.)

It set me to thinking – when is a win actually a draw? A very close game like this is a good candidate. On the other hand, a 63-25 score is a pretty unequivocal win.

The point spread limit that would indicate that one team’s victory over the other was just a matter of luck would depend on factors like:
  1. The point spread as a percentage of the score, 7-3 is more of a win in America football than 34-30.
  2. The typical scoring pattern in a type of game: a 3-0 win in soccer where few goals are scored is conclusive, whereas a 3-0 win in American football is a essentially a tie (and probably considered immoral, given that Americans like high scores in everything)
  3. The pattern over a series of games. If the Red team beats Blue consistently but always with a small margin, one could assume they’re the better team.
I’m hoping one of my Dear Readers will be able to point me to the appropriate research paper. I expect that these are the kinds of questions economists think about in their spare time.

Wednesday, January 04, 2006

His own sweet time

The nature of God is an 'innately hard problem', as I've defined it, since it's something the human mind can't grasp.

Anu Garg's New Year's Day greeting for Word.A.Day has a bearing on this:
A story goes that a man prays to God. God appears and the man says, "Lord! Our billions of years are your one second. Our billions of dollars are merely a penny for you. Could you grant me a penny?" God smiles, says "Certainly! Back in a second," and disappears.

Broadband Futures 1 - Who Pays?

The argument about “network neutrality” in the US is usually framed as Regulation vs. Markets, that is, it’s a fight over the value of unfettered Internet access vs. the wisdom of untrammeled markets. In fact, it’s about Who Pays.

The debate centers on the degree and kind of regulation of the next generation broadband consumer services in the US. The cable and telephone industries both offer broadband service, but have arrived at this point along different paths. Hence, they are governed by very different regulatory regimes. An attempt is under way to harmonize this regulation. Since the Internet is the driver of a great deal of new wealth, a lot is at stake.

Let’s consider the candidates in the Who Pays stakes.

First we have the customers for residential broadband Internet access. The cover a broad spectrum, from “passive” customers, who simply want to easy access entertainment, to “active” customers, who participate in a peer-to-peer web of content production.

Next, we have the network operators who provide this service; I’ll call them the ‘netops’. In fact, the service comes in two parts: the transport of packets, and applications and content these packets represent. The netops provide both.

Our third and fourth candidates provide applications and content services, but don’t transport packets. They are, respectively, the ‘establishment’ content providers, like eBay, Google, and Disney, and the ‘independent’ content providers. The independents cover a wide range from individual consumers, to new content providers like boingboing, to aggregators like digg and del.ico.us (independent until it was recently acquired by Yahoo), to application/content infrastructure that supports them like bittorrent and the P2P directories.

Next: What’s to be paid?

If we assume that the network needs to be upgraded to support high quality video streaming, then someone needs to bear the infrastructure build-out costs. If the current network suffices, or if the upgrade costs are small, there’s still the question of who retains the surplus value of new services, assuming that the next version of the Internet will generate abundant value which can be represented as money.

We can now get down to the nitty gritty: Who Pays?

The netops are not going to pay. They have sufficient market power, since they form a local duopoly, and even in some places a local monopoly. There are just two viable kinds high speed (ie faster than a few Mbps) Internet access in the foreseeable future, since only two industries have wire in the ground: the cable companies and the telephone companies. Wireless technology doesn’t offer enough bandwidth, and broadband over powerline doesn’t work. The netops will pass any costs on to the customers and/or the content providers, and will extract a share of revenue on new services from the content providers.

The independent content providers can’t pay. They don’t operate for profit, or they are not yet profitable. Their large numbers make the transaction costs of negotiating payments very high. The independents will rely on regulation to make either the establishment content providers, or the customers, pay. If they fail to do this, they will pay the ultimate price: the netops and/or the establishment will find ways to squeeze them into a marginal role.

The customers will pay through the fees they pay for Internet access. It’s possible but unlikely that they will be required to pay a premium to access to specific sites and services on the Internet, since this would generate a storm of protest about “Destroying The Internet As We Know It”, which would embarrass the netops. Rather, customers will pay for content indirectly. First, there will be a variety of bundles and tiers of service; customers will need to buy certain (expensive) tiers of service to get access specific types of service, eg Voice over IP, or streaming video, or P2P downloading. Second, netops will require content providers to pay to assure “enhanced” access for consumers to their sites. Depending on how competitive the market for a particular content service is, the content providers will either have to pay out of their profits, or pass the costs back to the consumers.

The establishment content providers will pay the netops in order to assure that their content gets through. The netops will require payment to ensure that content is delivered properly; whether it’s framed as a payment to “prevent degradation” or “provide better quality” is moot. It boils down to ensuring that a provider’s content is presented at least as well as that of their competitors. In some cases netops may try to block content, but this will be a delicate procedure, in terms of public relations. The notion that the Internet should be open to all comers is reasonably well established in the public mind. However, arguments about security and piracy will be used to constrain content, particularly that of the “can’t pay” independents; bittorrent streams and P2P applications in general come immediately to mind.

Tuesday, January 03, 2006

Software project management: an Innately Hard Problem

System Failure
The overruns in software projects demonstrate that our intuitions can be weak for knowledge goods. Our world is being filled with things our brains are not prepared for evolutionarily. Software is a prime example, and the frequent failures of large software projects is a symptom of a deeper problem than lack of project management skills.

This is an example of the class of ‘innately hard problems’, which our evolutionary heritage has not equipped us to solve instinctively. They’re different from 'intrinsically' hard problems like the halting problem in computer science, that is, problems which are hard to solve whether a human is involved or not.

Why we struggle to reason about software

Lakoff and Johnson [1] make a persuasive case that our methods of reasoning are grounded in our bodies, and our evolutionary history. Human artifacts which are not constrained by the physical natural world can confound our intuitions. It doesn’t mean we can’t build them, reason about them, or use them, but it does mean that we have to wary of assuming that our instincts about them will be correct.

Software is a good example of such an artifact. (Others include lotteries, quantum mechanics, exponential growth, very large or very small quantities, and financial markets.) Software is intangible and limitless [2] [3], and is built out of limitless intangibles – the ideas of programmers, and other pieces of software. Software modules can ‘call’ one another, ie delegate work by passing messages, essentially without limit. All these components become dependent on one another, and the permutations of who can call whom are unimaginably huge. Contrast this with a mechanical device, where the interactions between pieces is constrained by proximity, and are thus severely limited in number.

Software project overruns

Software projects are subject to overruns of mythic proportions, more so than other engineering tasks [4].

IEEE Spectrum devoted its September 2005 issue to software failures. It leads with a story on how the FBI blew more than $100 million on case-management software it will never use. In his review article, Robert Charrette summarizes the long, dismal history of IT projects gone awry. He mentions the giant British food retailer J Sainsbury PLC which wrote off its $526 million investment in an automated supply-chain management system last October. Back in 1981, to pick another example, the U.S. Federal Aviation Administration began looking into upgrading its antiquated air-traffic-control system. According to Charrette, the effort to build a replacement soon became riddled with problems; by 1994, when the agency finally gave up on the project, the predicted cost had tripled, more than $2.6 billion had been spent, and the expected delivery date had slipped by several years.

Charrette continues: “Of the IT projects that are initiated, from 5 to 15 percent will be abandoned before or shortly after delivery as hopelessly inadequate. Many others will arrive late and over budget or require massive reworking. Few IT projects, in other words, truly succeed.” He closes with this telling assessment: “Most IT experts agree that such failures occur far more often than they should. What's more, the failures are universally unprejudiced: they happen in every country; to large companies and small; in commercial, nonprofit, and governmental organizations; and without regard to status or reputation.”

IT failures happen more often than expected, everywhere, to everyone … There is something fundamental going on here.

Why do software projects fail?

In Waltzing with Bears, Tom Demarco and Timothy Lister boil software project risks down to five things: inherent schedule flaws, requirement creep, employee turnover, specification breakdown, and poor productivity. However, there’s nothing special about software here; these problems apply to any engineering project [5]. Further, they don’t explain why software failures are so much more dramatic than in other engineering disciplines.

The underlying reason for the surprising failure of large software projects is that the embodied intuitions of even the best managers, even after decades of experience, fail to the match the nature of what’s being managed.

Our mental models of projects are for building physical things. Toddlers play with building blocks, kids with Lego; even software games emulate physical reality. However, a physical structure and a piece of software are different in their degree of interconnectedness. If an outside wall of my house fails, it’s unlikely to bring down more than one corner. All the pieces of the house are connected, certainly, but their influence on each other decrease with distance. Large pieces of software consist of modules that are combined in infinite permutations: not only is the number large, one cannot predict at design time in what order the combinations will occur. Any module is instantly “reachable” from any other module. Here’s Robert Charette in IEEE again:

“All IT systems are intrinsically fragile. In a large brick building, you'd have to remove hundreds of strategically placed bricks to make a wall collapse. But in a 100 000-line software program, it takes only one or two bad lines to produce major problems. In 1991, a portion of AT&T’s telephone network went out, leaving 12 million subscribers without service, all because of a single mistyped character in one line of code.”

The failure is also omni-directional because of the non-physical interconnectedness of software systems. If the ground floor of a building is damaged, the whole building may collapse; however, one can remove the top floor without affecting the integrity of the rest of the structure. There is no force of gravity in software systems: errors can propagate in any direction.

Testing is the bottleneck in modern software systems development, and derives from the permutation problem. It’s easy to write a feature; but getting it tested as part of the whole may make it impossible to ship. Eric Lippert’s famous How many Microsoft employees does it take to change a lightbulb? explains how an “initial five minutes of dev time translates into many person-weeks of work and enormous costs.” While there are research projects in computer science to use advanced mathematics to make the permutation problem tractable, I don’t know of any that have proven their worth in shipping large code bases.

Comparisons with other branches of engineering

The success of silicon chip engineering shows that it’s not simply the exponential growth in the number of components that makes software engineering so unpredictable. Transistor density has been growing exponentially on silicon chips for decades. While fabrication plants are becoming fabulously complex, schedule miscalculations are far less severe than with software; slips are typically measured in quarters, not years. Software visionaries love to invoke Moore’s Law when talking about the future, but Moore was talking about hardware. Software’s ‘bang for the buck’ has not grown exponentially. When you next get a chance, ask your favorite software soothsayer why there’s no Moore’s Law for software.

Another telling characteristic of software slips is that they happen in the design phase. In other engineering projects, delays typically happen in production, not in design. Software is, of course, all design, all the time. Other engineering fields have robust models for the failure modes of their materials; we don’t have the equivalent models for ideas, the ingredients of software.

Saying that software engineering is still in its infancy isn’t an adequate explanation; it’s been going for at least fifty years. The SAGE early warning missile system was fully deployed in 1962, and led directly to the development of the SABRE air travel reservation system and later air traffic control systems. When SABRE debuted in 1964, it linked 2,000 terminals in sixty cities.

In sum: Physical metaphors of construction don’t apply to software. However, they’re all we have, when we think intuitively. Smart people can invent abstract tools, and we can learn heuristics to calculate answers, just as we can do in quantum mechanics. That doesn’t mean we understand either of them in our bones.

Update 3 Jan 05: fixed 'innately' for 'intrinsically' typo in second paragraph; thanks, S.

----- Notes -----

[1] Lakoff and Johnson’s Metaphors We Live By (1980) first brought this perspective to public attention. Their more recent Philosophy in the Flesh (1999) uses their notions of “embodied mind” to analyze systems of philosophical thought.

[2] Money is intangible, but limited in the sense that its ownership is a zero-sum game; either you have the money, or I do.

[3] Your ownership and use of a piece of software doesn’t impose any constraint on my enjoyment of it. This is only strictly true of “local software”. Software that is “hosted”, eg running on a central server and accessed by people across a network, is shared among all its users, and if there is sufficient demand your use of the software can impact mine. In both cases, though, the software is constructed out of other pieces of software, a compounding of intangibles.

[4] There is a good anecdotal evidence that software projects unravel more messily than other kinds. However, it’s hard to imagine how one could prove this statement, since a comparison would need detailed histories of all projects in at least two engineering fields. Building the histories would require the revelation of a great deal of sensitive information, whether by companies or governments.

[5] Lorin May provides a list of ten Major Causes of Software Project Failures in Crosstalk: The Journal of Defense Software Engineering. Wikipedia has a list of criticisms of software engineering, with rebuttals.